VRAM at 8K context
one agent, 8K context, q8_0 KV cache
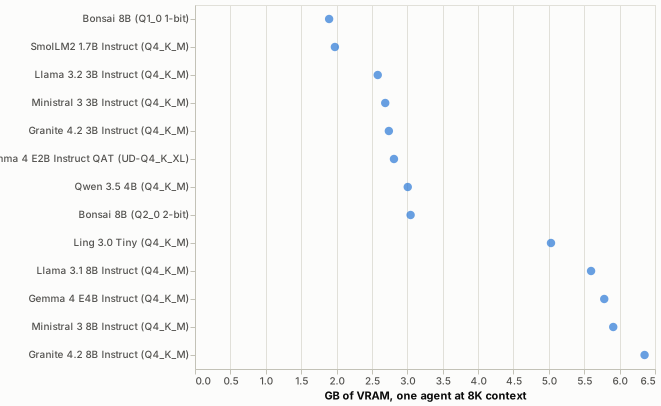
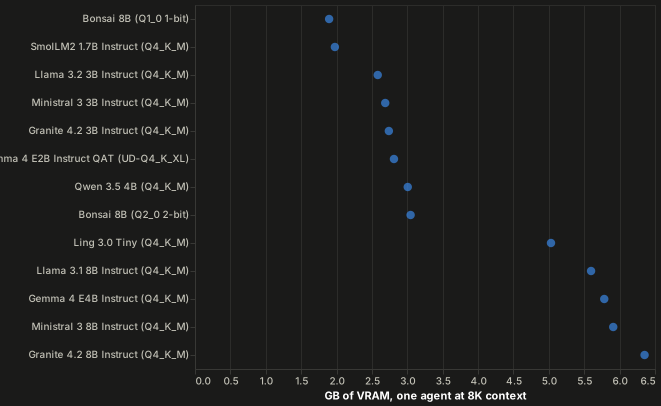
Graphics memory one agent needs, as llama.cpp reports it: the model weights, the KV cache for an 8,192-token context stored as q8_0, and the compute buffers. Every extra agent on the same model adds its own KV cache and compute buffers; the weights are shared.
VRAM at 8K context
Measured models
| Model | VRAM | Weights | KV cache | Compute | Rank | Family |
|---|---|---|---|---|---|---|
| Bonsai 8B (Q1_0 1-bit) | 1.90 GB | 1.15 GB | 0.64 GB | 0.10 GB | #1 of 13 | Bonsai |
| SmolLM2 1.7B Instruct (Q4_K_M) | 1.98 GB | 1.05 GB | 0.86 GB | 0.07 GB | #2 of 13 | SmolLM2 |
| Llama 3.2 3B Instruct (Q4_K_M) | 2.58 GB | 2.01 GB | 0.50 GB | 0.07 GB | #3 of 13 | Llama |
| Ministral 3 3B Instruct (Q4_K_M) | 2.69 GB | 2.14 GB | 0.46 GB | 0.09 GB | #4 of 13 | Ministral |
| Granite 4.2 3B Instruct (Q4_K_M) | 2.74 GB | 2.31 GB | 0.36 GB | 0.07 GB | #5 of 13 | Granite |
| Gemma 4 E2B Instruct QAT (UD-Q4_K_XL) | 2.81 GB | 2.60 GB | 0.08 GB | 0.13 GB | #6 of 13 | Gemma |
| Qwen 3.5 4B (Q4_K_M) | 3.01 GB | 2.73 GB | 0.20 GB | 0.08 GB | #7 of 13 | Qwen |
| Bonsai 8B (Q2_0 2-bit) | 3.05 GB | 2.30 GB | 0.64 GB | 0.10 GB | #8 of 13 | Bonsai |
| Ling 3.0 Tiny (Q4_K_M) | 5.03 GB | 4.91 GB | 0.05 GB | 0.07 GB | #9 of 13 | Ling |
| Llama 3.1 8B Instruct (Q4_K_M) | 5.60 GB | 4.91 GB | 0.57 GB | 0.11 GB | #10 of 13 | Llama |
| Gemma 4 E4B Instruct (Q4_K_M) | 5.78 GB | 5.39 GB | 0.25 GB | 0.14 GB | #11 of 13 | Gemma |
| Ministral 3 8B Instruct (Q4_K_M) | 5.91 GB | 5.19 GB | 0.61 GB | 0.11 GB | #12 of 13 | Ministral |
| Granite 4.2 8B Instruct (Q4_K_M) | 6.35 GB | 5.54 GB | 0.71 GB | 0.10 GB | #13 of 13 | Granite |
Model cards
- Bonsai 8B (Q1_0 1-bit)
- SmolLM2 1.7B Instruct (Q4_K_M)
- Llama 3.2 3B Instruct (Q4_K_M)
- Ministral 3 3B Instruct (Q4_K_M)
- Granite 4.2 3B Instruct (Q4_K_M)
- Gemma 4 E2B Instruct QAT (UD-Q4_K_XL)
- Qwen 3.5 4B (Q4_K_M)
- Bonsai 8B (Q2_0 2-bit)
- Ling 3.0 Tiny (Q4_K_M)
- Llama 3.1 8B Instruct (Q4_K_M)
- Gemma 4 E4B Instruct (Q4_K_M)
- Ministral 3 8B Instruct (Q4_K_M)
- Granite 4.2 8B Instruct (Q4_K_M)