Generation, 1K prompt
measured on one GPU
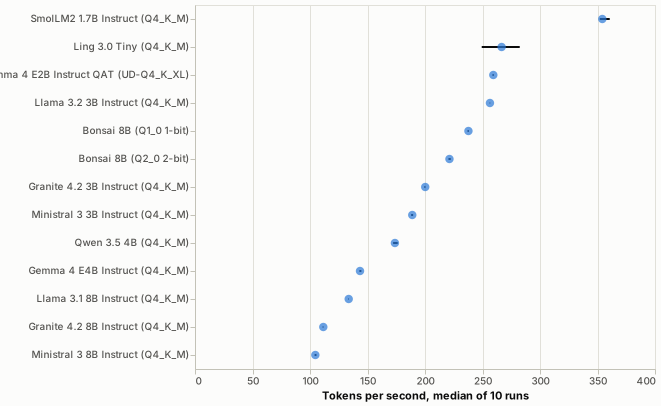
How fast the model writes its answer: tokens per second over 200 generated tokens, after a prompt of about 1,000 tokens. Greedy sampling, median of 10 runs.
Generation, 1K prompt
Measured models
| Model | Tokens/s | Interval | Rank range | Prompt tokens | Turn time | Family |
|---|---|---|---|---|---|---|
| SmolLM2 1.7B Instruct (Q4_K_M) | 354 tok/s | 352 to 361 | #1 of 13 | 1,193 | 0.69 s | SmolLM2 |
| Ling 3.0 Tiny (Q4_K_M) | 267 tok/s | 249 to 282 | #2–4 of 13 | 1,178 | 1.00 s | Ling |
| Gemma 4 E2B Instruct QAT (UD-Q4_K_XL) | 259 tok/s | 259 to 260 | #2–3 of 13 | 1,124 | 0.98 s | Gemma |
| Llama 3.2 3B Instruct (Q4_K_M) | 256 tok/s | 256 to 257 | #3–4 of 13 | 1,163 | 0.98 s | Llama |
| Bonsai 8B (Q1_0 1-bit) | 238 tok/s | 237 to 238 | #5 of 13 | 1,146 | 1.13 s | Bonsai |
| Bonsai 8B (Q2_0 2-bit) | 221 tok/s | 220 to 222 | #6 of 13 | 1,146 | 1.19 s | Bonsai |
| Granite 4.2 3B Instruct (Q4_K_M) | 200 tok/s | 199 to 200 | #7 of 13 | 1,169 | 1.23 s | Granite |
| Ministral 3 3B Instruct (Q4_K_M) | 189 tok/s | 188 to 190 | #8 of 13 | 1,163 | 1.62 s | Ministral |
| Qwen 3.5 4B (Q4_K_M) | 174 tok/s | 172 to 176 | #9 of 13 | 1,156 | 1.66 s | Qwen |
| Gemma 4 E4B Instruct (Q4_K_M) | 143 tok/s | 143 to 145 | #10 of 13 | 1,124 | 1.72 s | Gemma |
| Llama 3.1 8B Instruct (Q4_K_M) | 134 tok/s | 133 to 134 | #11 of 13 | 1,163 | 1.85 s | Llama |
| Granite 4.2 8B Instruct (Q4_K_M) | 112 tok/s | 111 to 112 | #12 of 13 | 1,169 | 2.15 s | Granite |
| Ministral 3 8B Instruct (Q4_K_M) | 105 tok/s | 104 to 106 | #13 of 13 | 1,163 | 2.42 s | Ministral |
Turn time is from sending the message to the last of 200 tokens, as the client sees it.
Model cards
- SmolLM2 1.7B Instruct (Q4_K_M)
- Ling 3.0 Tiny (Q4_K_M)
- Gemma 4 E2B Instruct QAT (UD-Q4_K_XL)
- Llama 3.2 3B Instruct (Q4_K_M)
- Bonsai 8B (Q1_0 1-bit)
- Bonsai 8B (Q2_0 2-bit)
- Granite 4.2 3B Instruct (Q4_K_M)
- Ministral 3 3B Instruct (Q4_K_M)
- Qwen 3.5 4B (Q4_K_M)
- Gemma 4 E4B Instruct (Q4_K_M)
- Llama 3.1 8B Instruct (Q4_K_M)
- Granite 4.2 8B Instruct (Q4_K_M)
- Ministral 3 8B Instruct (Q4_K_M)