Prefill, 4K prompt
measured on one GPU
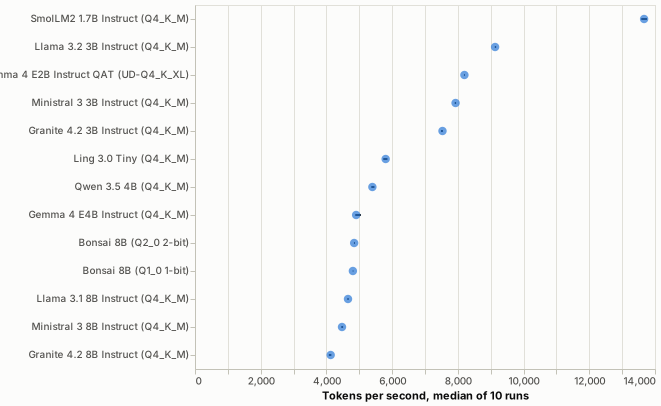
How fast the model reads a long prompt: prompt tokens per second for the character sheet with world notes, about 4,000 tokens. Longer prompts read a little slower per token.
Prefill, 4K prompt
Measured models
| Model | Tokens/s | Interval | Rank range | Prompt tokens | Prefill time | Family |
|---|---|---|---|---|---|---|
| SmolLM2 1.7B Instruct (Q4_K_M) | 13,668 tok/s | 13,582 to 13,757 | #1 of 13 | 4,058 | 0.30 s | SmolLM2 |
| Llama 3.2 3B Instruct (Q4_K_M) | 9,133 tok/s | 9,125 to 9,166 | #2 of 13 | 3,974 | 0.44 s | Llama |
| Gemma 4 E2B Instruct QAT (UD-Q4_K_XL) | 8,200 tok/s | 8,185 to 8,212 | #3 of 13 | 3,889 | 0.47 s | Gemma |
| Ministral 3 3B Instruct (Q4_K_M) | 7,930 tok/s | 7,904 to 7,947 | #4 of 13 | 4,024 | 0.51 s | Ministral |
| Granite 4.2 3B Instruct (Q4_K_M) | 7,532 tok/s | 7,486 to 7,547 | #5 of 13 | 4,018 | 0.53 s | Granite |
| Ling 3.0 Tiny (Q4_K_M) | 5,803 tok/s | 5,730 to 5,857 | #6 of 13 | 4,016 | 0.69 s | Ling |
| Qwen 3.5 4B (Q4_K_M) | 5,398 tok/s | 5,365 to 5,462 | #7 of 13 | 3,981 | 0.74 s | Qwen |
| Gemma 4 E4B Instruct (Q4_K_M) | 4,904 tok/s | 4,877 to 5,048 | #8 of 13 | 3,889 | 0.79 s | Gemma |
| Bonsai 8B (Q2_0 2-bit) | 4,844 tok/s | 4,836 to 4,867 | #9 of 13 | 3,959 | 0.82 s | Bonsai |
| Bonsai 8B (Q1_0 1-bit) | 4,805 tok/s | 4,800 to 4,820 | #10 of 13 | 3,959 | 0.82 s | Bonsai |
| Llama 3.1 8B Instruct (Q4_K_M) | 4,657 tok/s | 4,635 to 4,680 | #11 of 13 | 3,974 | 0.85 s | Llama |
| Ministral 3 8B Instruct (Q4_K_M) | 4,474 tok/s | 4,452 to 4,508 | #12 of 13 | 4,024 | 0.90 s | Ministral |
| Granite 4.2 8B Instruct (Q4_K_M) | 4,130 tok/s | 4,073 to 4,150 | #13 of 13 | 4,018 | 0.97 s | Granite |
Model cards
- SmolLM2 1.7B Instruct (Q4_K_M)
- Llama 3.2 3B Instruct (Q4_K_M)
- Gemma 4 E2B Instruct QAT (UD-Q4_K_XL)
- Ministral 3 3B Instruct (Q4_K_M)
- Granite 4.2 3B Instruct (Q4_K_M)
- Ling 3.0 Tiny (Q4_K_M)
- Qwen 3.5 4B (Q4_K_M)
- Gemma 4 E4B Instruct (Q4_K_M)
- Bonsai 8B (Q2_0 2-bit)
- Bonsai 8B (Q1_0 1-bit)
- Llama 3.1 8B Instruct (Q4_K_M)
- Ministral 3 8B Instruct (Q4_K_M)
- Granite 4.2 8B Instruct (Q4_K_M)