Generation, 4K prompt
measured on one GPU
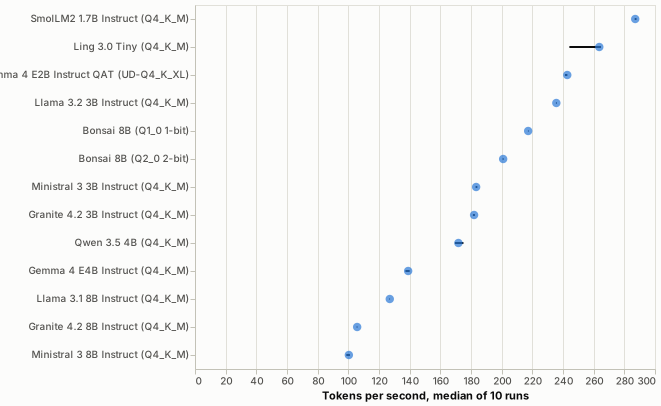
Writing speed deeper into the context: tokens per second over 200 generated tokens after a prompt of about 4,000 tokens. Each new token attends to the whole prompt, so this is slower than after a short prompt.
Generation, 4K prompt
Measured models
| Model | Tokens/s | Interval | Rank range | Prompt tokens | Turn time | Family |
|---|---|---|---|---|---|---|
| SmolLM2 1.7B Instruct (Q4_K_M) | 287 tok/s | 287 to 288 | #1 of 13 | 4,058 | 1.03 s | SmolLM2 |
| Ling 3.0 Tiny (Q4_K_M) | 264 tok/s | 244 to 265 | #2 of 13 | 4,016 | 1.53 s | Ling |
| Gemma 4 E2B Instruct QAT (UD-Q4_K_XL) | 243 tok/s | 241 to 243 | #3 of 13 | 3,889 | 1.37 s | Gemma |
| Llama 3.2 3B Instruct (Q4_K_M) | 236 tok/s | 235 to 236 | #4 of 13 | 3,974 | 1.36 s | Llama |
| Bonsai 8B (Q1_0 1-bit) | 217 tok/s | 217 to 218 | #5 of 13 | 3,959 | 1.80 s | Bonsai |
| Bonsai 8B (Q2_0 2-bit) | 201 tok/s | 201 to 201 | #6 of 13 | 3,959 | 1.86 s | Bonsai |
| Ministral 3 3B Instruct (Q4_K_M) | 183 tok/s | 183 to 184 | #7 of 13 | 4,024 | 1.90 s | Ministral |
| Granite 4.2 3B Instruct (Q4_K_M) | 182 tok/s | 181 to 183 | #8 of 13 | 4,018 | 1.71 s | Granite |
| Qwen 3.5 4B (Q4_K_M) | 172 tok/s | 170 to 175 | #9 of 13 | 3,981 | 2.15 s | Qwen |
| Gemma 4 E4B Instruct (Q4_K_M) | 139 tok/s | 137 to 140 | #10 of 13 | 3,889 | 2.30 s | Gemma |
| Llama 3.1 8B Instruct (Q4_K_M) | 127 tok/s | 127 to 127 | #11 of 13 | 3,974 | 2.51 s | Llama |
| Granite 4.2 8B Instruct (Q4_K_M) | 106 tok/s | 105 to 106 | #12 of 13 | 4,018 | 2.95 s | Granite |
| Ministral 3 8B Instruct (Q4_K_M) | 100 tok/s | 99 to 101 | #13 of 13 | 4,024 | 3.16 s | Ministral |
Turn time is from sending the message to the last of 200 tokens, as the client sees it.
Model cards
- SmolLM2 1.7B Instruct (Q4_K_M)
- Ling 3.0 Tiny (Q4_K_M)
- Gemma 4 E2B Instruct QAT (UD-Q4_K_XL)
- Llama 3.2 3B Instruct (Q4_K_M)
- Bonsai 8B (Q1_0 1-bit)
- Bonsai 8B (Q2_0 2-bit)
- Ministral 3 3B Instruct (Q4_K_M)
- Granite 4.2 3B Instruct (Q4_K_M)
- Qwen 3.5 4B (Q4_K_M)
- Gemma 4 E4B Instruct (Q4_K_M)
- Llama 3.1 8B Instruct (Q4_K_M)
- Granite 4.2 8B Instruct (Q4_K_M)
- Ministral 3 8B Instruct (Q4_K_M)