Prefill, 1K prompt
measured on one GPU
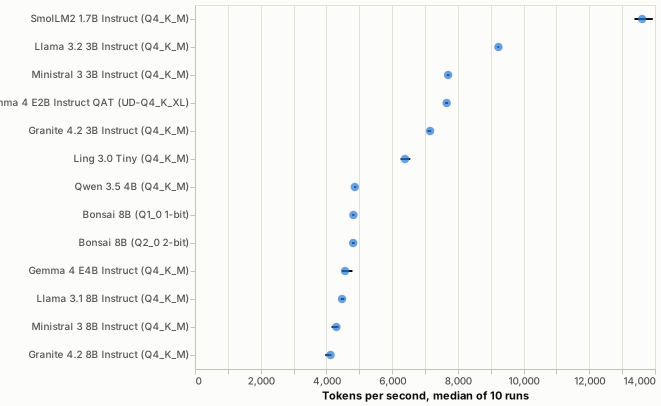
How fast the model reads its prompt before it can answer: prompt tokens per second for a character sheet of about 1,000 tokens. The median of 10 runs, each with a fresh agent, timed by llama.cpp's own counters.
Prefill, 1K prompt
Measured models
| Model | Tokens/s | Interval | Rank range | Prompt tokens | Prefill time | Family |
|---|---|---|---|---|---|---|
| SmolLM2 1.7B Instruct (Q4_K_M) | 13,609 tok/s | 13,376 to 13,932 | #1 of 13 | 1,193 | 0.09 s | SmolLM2 |
| Llama 3.2 3B Instruct (Q4_K_M) | 9,236 tok/s | 9,203 to 9,256 | #2 of 13 | 1,163 | 0.13 s | Llama |
| Ministral 3 3B Instruct (Q4_K_M) | 7,703 tok/s | 7,668 to 7,747 | #3–4 of 13 | 1,163 | 0.15 s | Ministral |
| Gemma 4 E2B Instruct QAT (UD-Q4_K_XL) | 7,659 tok/s | 7,611 to 7,703 | #3–4 of 13 | 1,124 | 0.15 s | Gemma |
| Granite 4.2 3B Instruct (Q4_K_M) | 7,155 tok/s | 7,078 to 7,187 | #5 of 13 | 1,169 | 0.16 s | Granite |
| Ling 3.0 Tiny (Q4_K_M) | 6,393 tok/s | 6,256 to 6,553 | #6 of 13 | 1,178 | 0.18 s | Ling |
| Qwen 3.5 4B (Q4_K_M) | 4,864 tok/s | 4,844 to 4,907 | #7–9 of 13 | 1,156 | 0.24 s | Qwen |
| Bonsai 8B (Q1_0 1-bit) | 4,822 tok/s | 4,787 to 4,849 | #7–10 of 13 | 1,146 | 0.24 s | Bonsai |
| Bonsai 8B (Q2_0 2-bit) | 4,814 tok/s | 4,780 to 4,857 | #7–10 of 13 | 1,146 | 0.24 s | Bonsai |
| Gemma 4 E4B Instruct (Q4_K_M) | 4,567 tok/s | 4,466 to 4,793 | #8–11 of 13 | 1,124 | 0.25 s | Gemma |
| Llama 3.1 8B Instruct (Q4_K_M) | 4,474 tok/s | 4,437 to 4,544 | #10–11 of 13 | 1,163 | 0.26 s | Llama |
| Ministral 3 8B Instruct (Q4_K_M) | 4,303 tok/s | 4,157 to 4,370 | #12 of 13 | 1,163 | 0.27 s | Ministral |
| Granite 4.2 8B Instruct (Q4_K_M) | 4,126 tok/s | 3,965 to 4,152 | #13 of 13 | 1,169 | 0.28 s | Granite |
Model cards
- SmolLM2 1.7B Instruct (Q4_K_M)
- Llama 3.2 3B Instruct (Q4_K_M)
- Ministral 3 3B Instruct (Q4_K_M)
- Gemma 4 E2B Instruct QAT (UD-Q4_K_XL)
- Granite 4.2 3B Instruct (Q4_K_M)
- Ling 3.0 Tiny (Q4_K_M)
- Qwen 3.5 4B (Q4_K_M)
- Bonsai 8B (Q1_0 1-bit)
- Bonsai 8B (Q2_0 2-bit)
- Gemma 4 E4B Instruct (Q4_K_M)
- Llama 3.1 8B Instruct (Q4_K_M)
- Ministral 3 8B Instruct (Q4_K_M)
- Granite 4.2 8B Instruct (Q4_K_M)