Tool calls, BFCL
BFCL v4 slice, one greedy pass
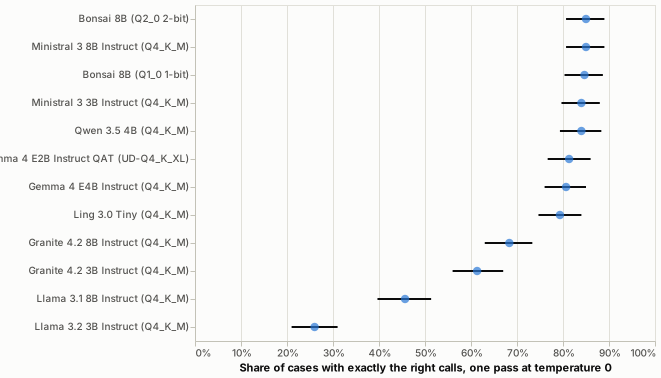
Single requests from the Berkeley Function Calling Leaderboard (BFCL v4), a public tool-calling test: one call, picking between several tools, several calls at once, and requests no tool fits. A case counts only when the calls match an accepted answer exactly. One pass per case at temperature 0, through the Tryll ToolCall node, so the numbers are not the same as the public BFCL leaderboard.
Every model on this page was measured on NVIDIA GeForce RTX 4080 · Vulkan.
Tool calls, BFCL
Measured models
| Model | Right | Interval | Rank range | Cases | Most common mistake | Family |
|---|---|---|---|---|---|---|
| Bonsai 8B (Q2_0 2-bit) | 85.0% | 80.7% to 89.0% | #1–5 of 12 | 255 of 300 | wrong argument value (33) | Bonsai |
| Ministral 3 8B Instruct (Q4_K_M) | 85.0% | 80.7% to 89.0% | #1–5 of 12 | 255 of 300 | wrong argument value (32) | Ministral |
| Bonsai 8B (Q1_0 1-bit) | 84.7% | 80.3% to 88.7% | #1–6 of 12 | 254 of 300 | wrong argument value (33) | Bonsai |
| Ministral 3 3B Instruct (Q4_K_M) | 84.0% | 79.7% to 88.0% | #1–7 of 12 | 252 of 300 | wrong argument value (34) | Ministral |
| Qwen 3.5 4B (Q4_K_M) | 84.0% | 79.3% to 88.3% | #1–7 of 12 | 252 of 300 | wrong argument value (33) | Qwen |
| Gemma 4 E2B Instruct QAT (UD-Q4_K_XL) | 81.3% | 76.7% to 86.0% | #3–8 of 12 | 244 of 300 | wrong argument value (30) | Gemma |
| Gemma 4 E4B Instruct (Q4_K_M) | 80.7% | 76.0% to 85.0% | #4–8 of 12 | 242 of 300 | wrong argument value (35) | Gemma |
| Ling 3.0 Tiny (Q4_K_M) | 79.3% | 74.7% to 84.0% | #6–8 of 12 | 238 of 300 | wrong argument value (37) | Ling |
| Granite 4.2 8B Instruct (Q4_K_M) | 68.3% | 63.0% to 73.3% | #9 of 12 | 205 of 300 | missed a call (57) | Granite |
| Granite 4.2 3B Instruct (Q4_K_M) | 61.3% | 56.0% to 67.0% | #10 of 12 | 184 of 300 | missed a call (88) | Granite |
| Llama 3.1 8B Instruct (Q4_K_M) | 45.7% | 39.7% to 51.3% | #11 of 12 | 137 of 300 | missed a call (57) | Llama |
| Llama 3.2 3B Instruct (Q4_K_M) | 26.0% | 21.0% to 31.0% | #12 of 12 | 78 of 300 | right value, wrong type (100) | Llama |
Model cards
- Bonsai 8B (Q2_0 2-bit)
- Ministral 3 8B Instruct (Q4_K_M)
- Bonsai 8B (Q1_0 1-bit)
- Ministral 3 3B Instruct (Q4_K_M)
- Qwen 3.5 4B (Q4_K_M)
- Gemma 4 E2B Instruct QAT (UD-Q4_K_XL)
- Gemma 4 E4B Instruct (Q4_K_M)
- Ling 3.0 Tiny (Q4_K_M)
- Granite 4.2 8B Instruct (Q4_K_M)
- Granite 4.2 3B Instruct (Q4_K_M)
- Llama 3.1 8B Instruct (Q4_K_M)
- Llama 3.2 3B Instruct (Q4_K_M)
No tool support: SmolLM2 1.7B Instruct (Q4_K_M).